Constraint Success Rate (CSR) measures the proportion of individual constraints that are correctly satisfied by the model's response. Instruction Success Rate (ISR) measures the proportion of instructions for which all constraints are satisfied.
The current leaderboard covers small (1.5–4B), medium (>4–32B) and large (>32B) open-weight models; results for proprietary models will be added as they are evaluated.
Current setting
Judge gpt-5.6-luna; every (model, mode) is sampled 3 times independently with the
vendor-recommended decoding parameters. [T] = thinking mode, [N] = non-thinking mode.
CSR and ISR are mean ± sample std over the 3 runs; the remaining columns are the
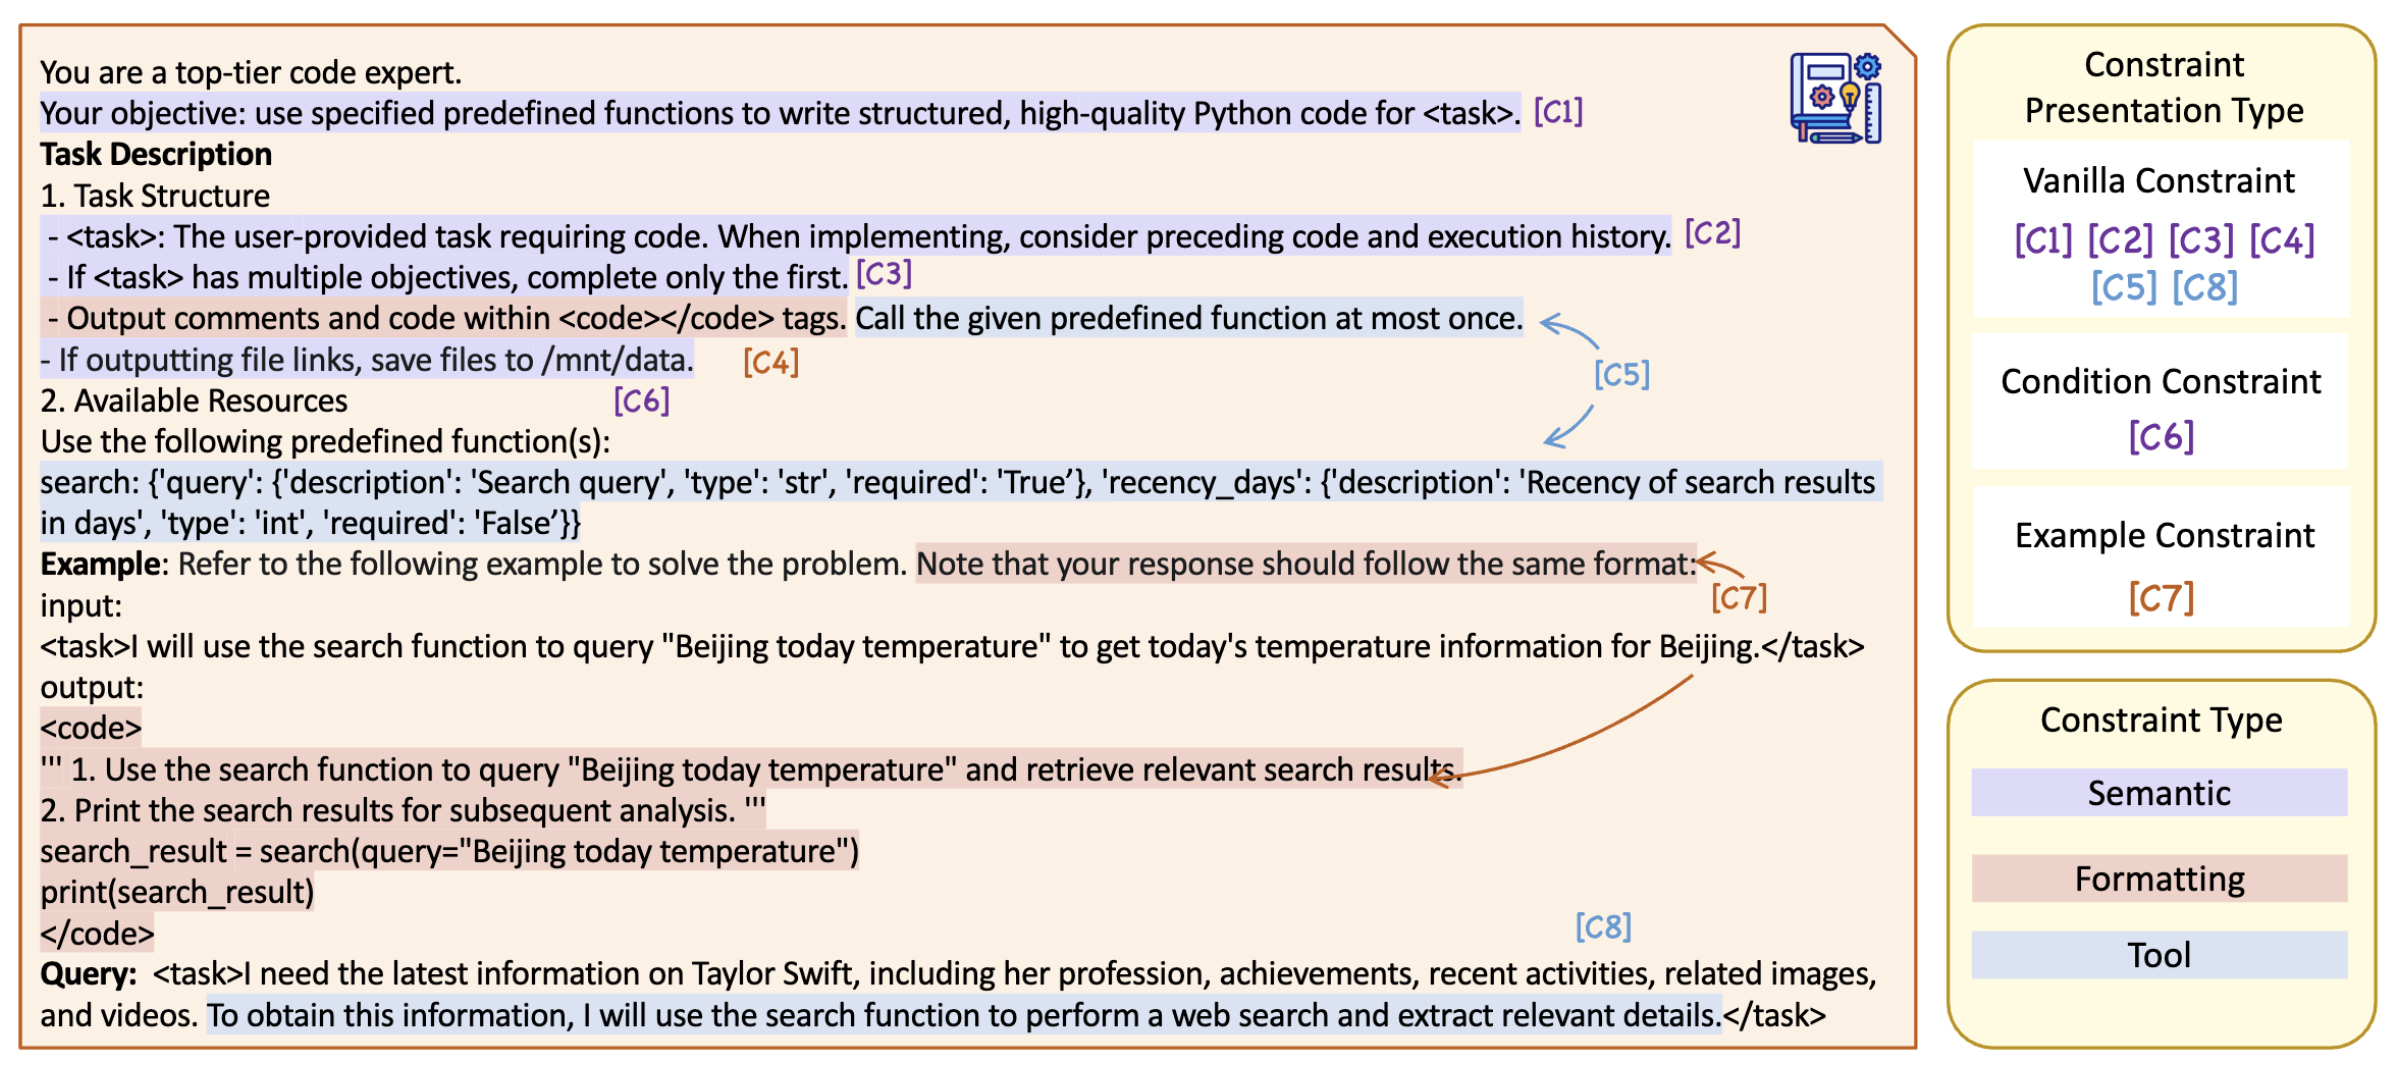
mean CSR per constraint presentation type (Vanilla / Condition / Example) and per constraint type
(Formatting / Semantic / Tool). By default the table shows thinking-mode results sorted by CSR; use the
dropdowns to change the sort metric, switch to non-thinking results, or filter by model size. Column
headers are also clickable for sorting, and clicking a model opens its exact vLLM flags and sampling parameters.
| Overall | Presentation Type | Constraint Type | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| # | Model | Size | CSR | ISR | Vanilla | Condition | Example | Formatting | Semantic | Tool |
| [T]DeepSeek-V4-Pro | Large | 67.44 ± 0.59 | 31.27 ± 1.54 | 67.94 | 51.76 | 82.24 | 72.79 | 67.85 | 53.38 | |
| [T]Qwen3.8-27B | Medium | 65.77 ± 0.41 | 31.35 ± 0.36 | 66.98 | 49.03 | 77.37 | 69.38 | 67.15 | 51.93 | |
| [T]Qwen3.8-Flash | Large | 65.59 ± 0.59 | 27.35 ± 0.22 | 66.03 | 49.89 | 80.80 | 71.82 | 66.18 | 51.13 | |
| [T]Qwen3.5-9B | Medium | 65.33 ± 0.26 | 30.36 ± 0.59 | 66.73 | 48.50 | 76.38 | 69.42 | 65.60 | 53.80 | |
| [T]Kimi-K3 | Large | 64.89 ± 0.35 | 26.12 ± 1.08 | 66.31 | 46.56 | 75.99 | 67.39 | 66.91 | 51.16 | |
| [T]Gemma-4-31B-it | Medium | 64.79 ± 0.42 | 29.80 ± 0.33 | 64.57 | 51.29 | 82.12 | 68.89 | 66.11 | 50.66 | |
| [N]Gemma-4-31B-it | Medium | 64.67 ± 0.23 | 26.12 ± 0.73 | 64.38 | 51.70 | 82.05 | 67.44 | 66.28 | 51.51 | |
| [T]GLM-5.3-Flash | Large | 64.43 ± 0.19 | 24.89 ± 0.37 | 65.92 | 46.16 | 75.95 | 65.97 | 68.19 | 45.50 | |
| [T]GLM-5.3 | Large | 64.21 ± 0.26 | 27.06 ± 1.04 | 65.91 | 45.39 | 73.95 | 66.45 | 67.25 | 47.18 | |
| [N]Qwen3.5-9B | Medium | 63.56 ± 0.66 | 26.45 ± 0.62 | 65.26 | 48.28 | 70.53 | 65.13 | 65.44 | 52.13 | |
| [N]Qwen3.8-Flash | Large | 63.39 ± 1.22 | 29.56 ± 0.51 | 64.12 | 49.34 | 74.92 | 72.61 | 60.87 | 51.92 | |
| [T]Gemma-4-12B-it | Medium | 63.16 ± 0.26 | 27.82 ± 0.64 | 64.55 | 50.66 | 68.99 | 64.15 | 65.60 | 52.86 | |
| [N]Gemma-4-E4B-it | Small | 62.96 ± 0.80 | 26.87 ± 0.14 | 64.64 | 50.76 | 67.43 | 65.19 | 65.34 | 48.87 | |
| [N]Gemma-4-12B-it | Medium | 62.35 ± 0.55 | 24.71 ± 0.70 | 61.89 | 51.22 | 78.13 | 63.06 | 64.34 | 54.46 | |
| [T]Qwen3.5-4B | Small | 62.34 ± 1.09 | 26.54 ± 0.41 | 63.34 | 47.25 | 73.38 | 64.86 | 63.41 | 51.78 | |
| [N]Qwen3.8-27B | Medium | 62.03 ± 0.69 | 26.54 ± 0.22 | 63.05 | 50.04 | 69.46 | 64.61 | 62.85 | 53.52 | |
| [T]MiniMax-M2.7 | Large | 61.88 ± 0.21 | 22.07 ± 0.75 | 63.06 | 48.88 | 69.42 | 65.51 | 62.10 | 53.41 | |
| [T]Gemma-4-E4B-it | Small | 61.65 ± 0.39 | 25.70 ± 0.80 | 62.12 | 48.24 | 74.61 | 61.68 | 63.83 | 53.70 | |
| [T]Nemotron-Nano-9B-v2 | Medium | 61.17 ± 0.74 | 25.66 ± 0.55 | 61.44 | 46.45 | 75.96 | 68.54 | 58.00 | 56.56 | |
| [T]Gemma-4-E2B-it | Small | 61.04 ± 0.17 | 25.65 ± 1.28 | 62.71 | 47.65 | 66.57 | 64.13 | 61.66 | 51.12 | |
| [N]Qwen3.5-4B | Small | 60.98 ± 0.48 | 22.96 ± 0.94 | 62.71 | 47.94 | 64.93 | 62.28 | 62.95 | 50.20 | |
| [N]Nemotron-Nano-9B-v2 | Medium | 60.39 ± 0.43 | 24.99 ± 0.41 | 61.06 | 42.83 | 74.30 | 68.42 | 57.05 | 54.23 | |
| [N]Gemma-4-E2B-it | Small | 60.31 ± 0.73 | 24.99 ± 1.19 | 63.00 | 45.25 | 61.85 | 61.42 | 62.99 | 46.76 | |
| [T]DeepSeek-R1-0528-Qwen3-8B | Medium | 59.93 ± 0.10 | 26.50 ± 0.57 | 60.63 | 47.03 | 70.66 | 62.96 | 59.96 | 52.83 | |
| [T]Granite-4.2-3B | Small | 58.78 ± 0.55 | 28.95 ± 1.66 | 62.99 | 39.42 | 53.01 | 60.23 | 58.92 | 53.43 | |
| [N]Nemotron-3-Nano-4B | Small | 58.50 ± 0.30 | 24.56 ± 0.22 | 59.78 | 39.13 | 71.40 | 68.93 | 54.37 | 47.94 | |
| [N]Ministral-3-3B-Instruct-2512 | Small | 55.93 ± 0.26 | 19.28 ± 0.85 | 57.83 | 44.55 | 57.61 | 50.17 | 60.00 | 52.50 | |
| [T]Qwen3.5-2B | Small | 55.83 ± 0.16 | 21.64 ± 0.99 | 58.78 | 42.29 | 53.12 | 59.03 | 56.45 | 44.76 | |
| [T]Nemotron-3-Nano-4B | Small | 55.60 ± 0.35 | 25.08 ± 0.29 | 58.58 | 38.58 | 54.98 | 59.10 | 53.79 | 52.85 | |
| [N]Granite-4.2-3B | Small | 55.20 ± 0.35 | 23.24 ± 0.80 | 59.41 | 37.91 | 48.51 | 51.78 | 57.91 | 50.95 | |
| [T]gpt-oss-20b | Medium | 54.97 ± 0.30 | 24.66 ± 0.78 | 58.19 | 45.99 | 43.95 | 51.14 | 57.49 | 55.55 | |
| [T]Hunyuan-4B-Instruct | Small | 54.35 ± 0.18 | 18.10 ± 0.24 | 56.01 | 38.78 | 60.01 | 57.99 | 54.97 | 44.14 | |
| [T]MiniCPM5-2B | Small | 54.21 ± 0.45 | 21.92 ± 0.14 | 55.83 | 44.47 | 54.99 | 54.35 | 55.30 | 50.49 | |
| [T]Ministral-3-3B-Reasoning-2512 | Small | 53.82 ± 0.45 | 20.51 ± 0.28 | 55.48 | 38.61 | 59.50 | 52.07 | 55.25 | 51.82 | |
| [N]MiniCPM5-2B | Small | 52.35 ± 0.83 | 19.57 ± 0.22 | 55.27 | 44.47 | 42.57 | 52.19 | 53.31 | 49.99 | |
| [N]Qwen3.5-2B | Small | 50.10 ± 0.41 | 16.31 ± 0.90 | 53.72 | 36.01 | 43.63 | 50.59 | 50.15 | 46.24 | |
| [N]Hunyuan-4B-Instruct | Small | 43.93 ± 0.17 | 10.23 ± 0.43 | 46.43 | 33.61 | 39.02 | 34.22 | 50.60 | 42.45 | |
Success rates (%) on AgentIF under the current setting.
Size groups follow total parameter count: Small Open = 1.5–4B, Medium Open = >4–32B,
Large Open = >32B. Small and medium models are served locally with vLLM; large models are called through
their official APIs with the same sampling parameters.
The exact vLLM flags and sampling parameters of every row are the committed
configs/<model>.yaml files.
Last Update: 2026-10-11
Legacy results — original setting (judge gpt-4o-2024-11-20, single greedy run)
Produced with the original protocol: judge gpt-4o-2024-11-20 with temperature 0, one greedy run
per model, API models called with their default mode. Kept for reference only;
not comparable with the table above. Click a model to download its full results, or browse the
complete results repository.
| Presentation Type | Constraint Type | Overall | |||||||
|---|---|---|---|---|---|---|---|---|---|
| # | Model | Vanilla | Condition | Example | Formatting | Semantic | Tool | ISR | CSR |
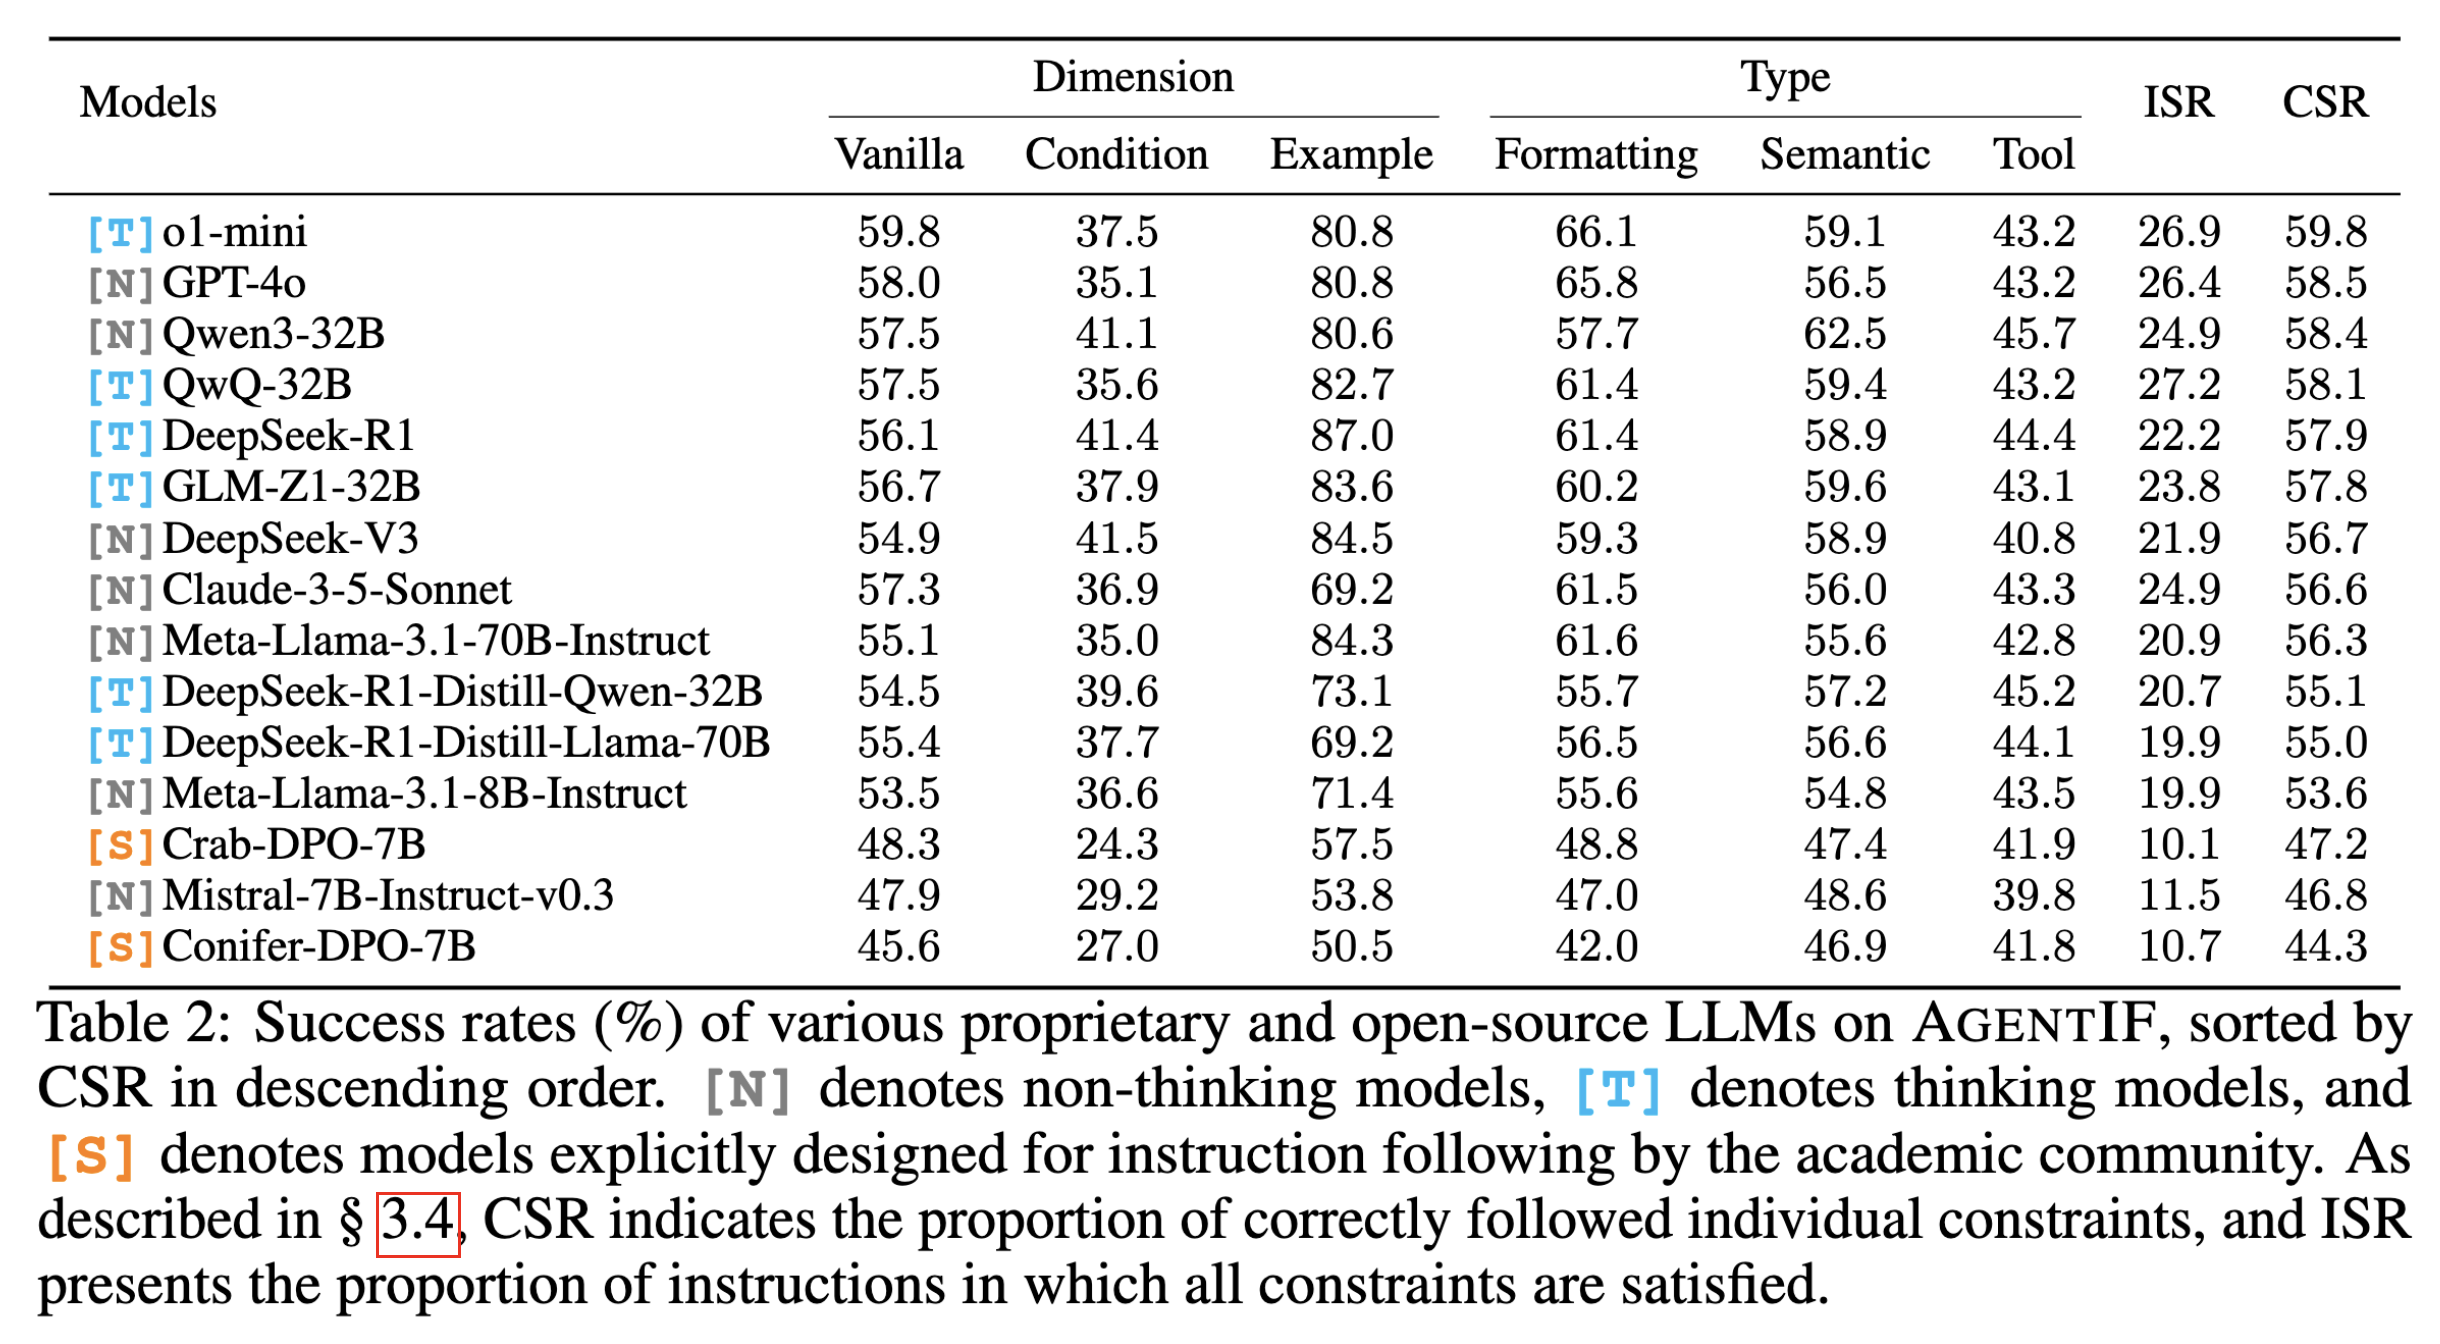
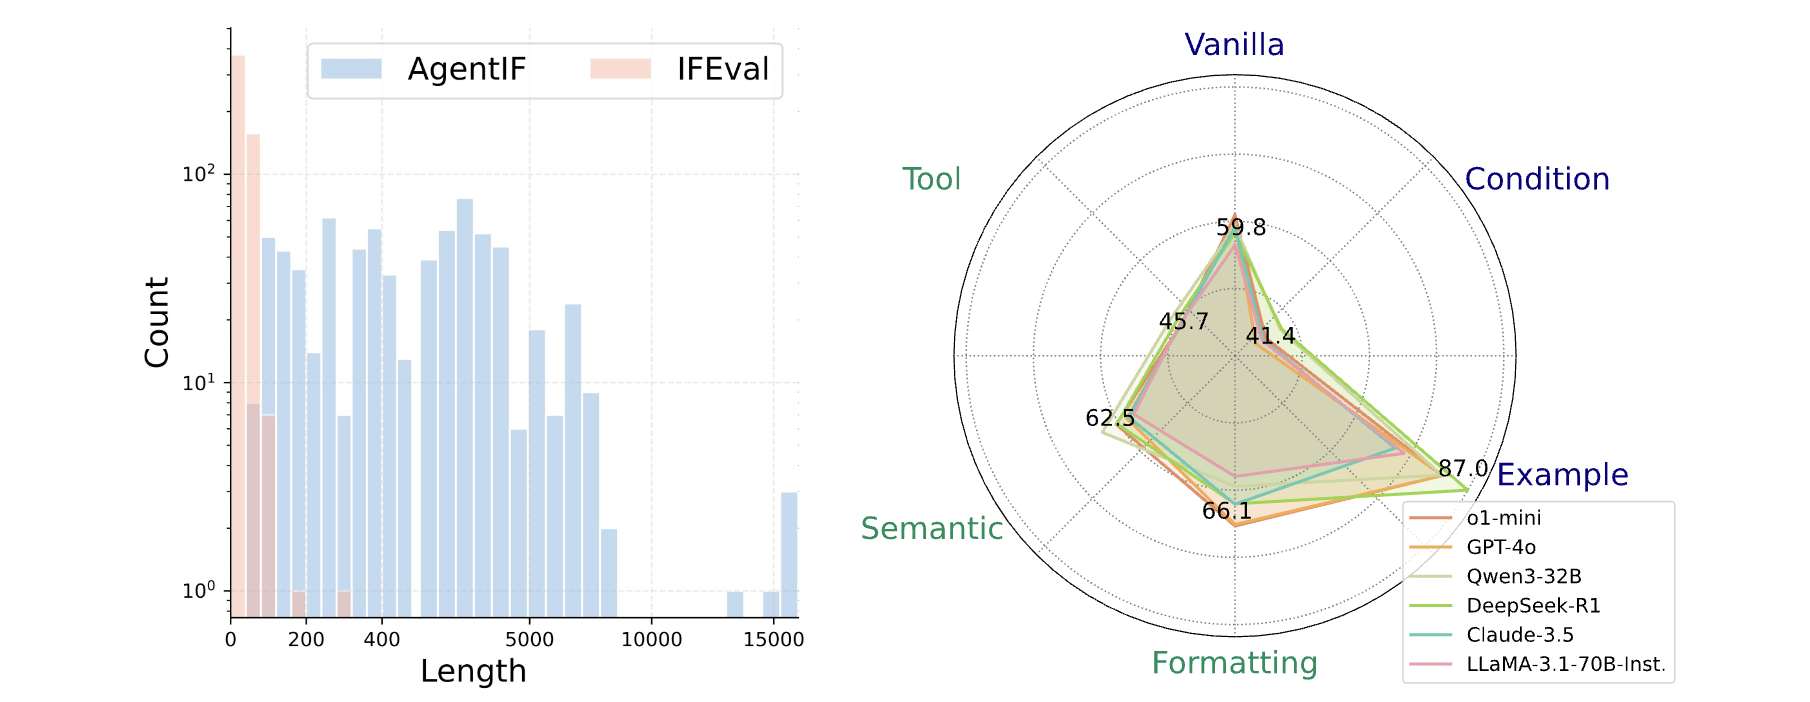
| [T]o1-mini | 59.8 | 37.5 | 80.8 | 66.1 | 59.1 | 43.2 | 26.9 | 59.8 | |
| [N]GPT-4o | 58.0 | 35.1 | 80.8 | 65.8 | 56.5 | 43.2 | 26.4 | 58.5 | |
| [N]Qwen3-32B | 57.5 | 41.1 | 80.6 | 57.7 | 62.5 | 45.7 | 24.9 | 58.4 | |
| [T]QwQ-32B | 57.5 | 35.6 | 82.7 | 61.4 | 59.4 | 43.2 | 27.2 | 58.1 | |
| [T]DeepSeek-R1 | 56.1 | 41.4 | 87.0 | 61.4 | 58.9 | 44.4 | 22.2 | 57.9 | |
| [T]GLM-Z1-32B | 56.7 | 37.9 | 83.6 | 60.2 | 59.6 | 43.1 | 23.8 | 57.8 | |
| [N]DeepSeek-V3 | 54.9 | 41.5 | 84.5 | 59.3 | 58.9 | 40.8 | 21.9 | 56.7 | |
| [N]Claude-3-5-Sonnet | 57.3 | 36.9 | 69.2 | 61.5 | 56.0 | 43.3 | 24.9 | 56.6 | |
| [N]Meta-Llama-3.1-70B-Instruct | 55.1 | 35.0 | 84.3 | 61.6 | 55.6 | 42.8 | 20.9 | 56.3 | |
| [T]DeepSeek-R1-Distill-Qwen-32B | 54.5 | 39.6 | 73.1 | 55.7 | 57.2 | 45.2 | 20.7 | 55.1 | |
| [T]DeepSeek-R1-Distill-Llama-70B | 55.4 | 37.7 | 69.2 | 56.5 | 56.6 | 44.1 | 19.9 | 55.0 | |
| [N]Meta-Llama-3.1-8B-Instruct | 53.5 | 36.6 | 71.4 | 55.6 | 54.8 | 43.5 | 19.9 | 53.6 | |
| [S]Crab-DPO-7B | 48.3 | 24.3 | 57.5 | 48.8 | 47.4 | 41.9 | 10.1 | 47.2 | |
| [N]Mistral-7B-Instruct-v0.3 | 47.9 | 29.2 | 53.8 | 47.0 | 48.6 | 39.8 | 11.5 | 46.8 | |
| [S]Conifer-DPO-7B | 45.6 | 27.0 | 50.5 | 42.0 | 46.9 | 41.8 | 10.7 | 44.3 | |
Success rates (%) of various proprietary and open-source LLMs on AgentIF under the original setting, sorted by CSR in descending order by default. [N] denotes non-thinking models, [T] denotes thinking models, and [S] denotes models explicitly designed for instruction following by the academic community. Last update of this table: 2025-06-10.
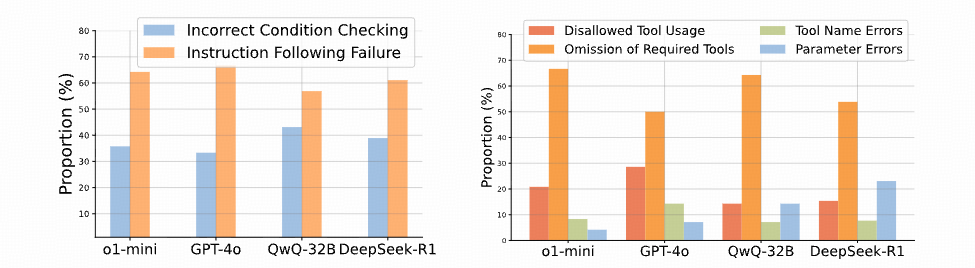
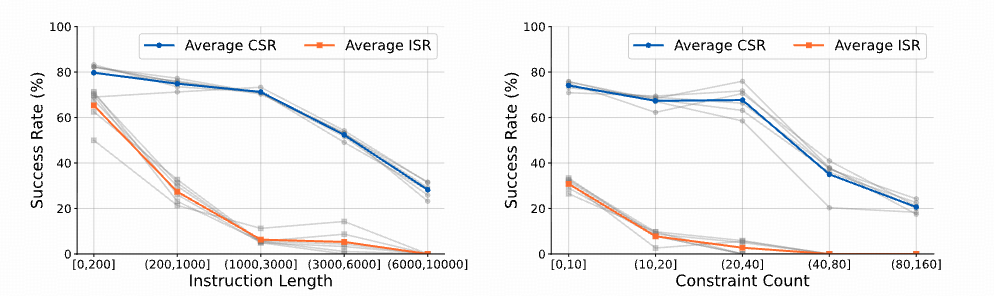
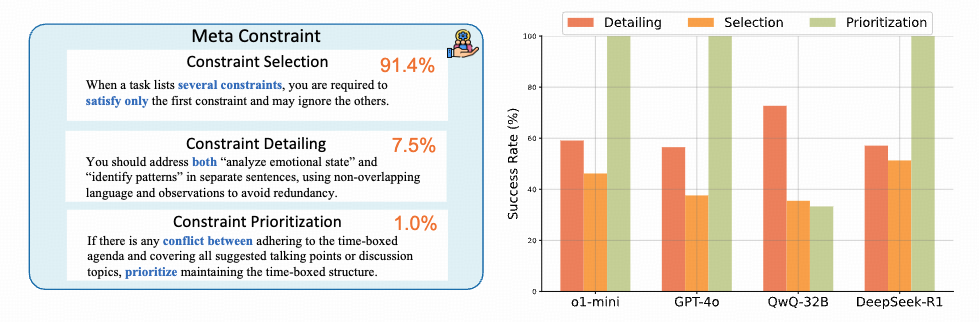
Performance across constraint categories reported in the paper (original setting):